Integrating Football Metrics and Equine Performance Data for Stable Accumulator Construction
Written by Vera Sullivan · Jun 15, 2026
Integrating Football Metrics and Equine Performance Data for Stable Accumulator Construction
Analysts across betting operations have increasingly turned to cross-discipline data fusion as a method for strengthening multi-leg wagers that combine football and horse racing selections. League analytics supply granular details on team possession rates, expected goals, and player availability, while track statistics deliver speed ratings, sectional times, and surface preferences. When these datasets merge through shared modeling frameworks, the resulting structures show reduced sensitivity to isolated upsets in either sport.
Researchers at institutions studying predictive modeling note that football variables such as set-piece conversion percentages and progressive pass volumes interact with racing factors including draw bias and going descriptions. This interaction creates correlation matrices that adjust stake allocation across legs rather than treating each selection as independent. Data fusion techniques apply weighted algorithms that recalibrate probabilities when early legs in a chain produce unexpected results, allowing later selections to absorb variance without collapsing the entire wager.
Core Components of League Analytics in Accumulator Design
Football datasets typically include advanced metrics from multiple European and domestic competitions. Expected threat values, pressing intensity indices, and goalkeeper distribution accuracy feed into regression models that estimate match outcomes with quantified confidence intervals. Observers note that these inputs gain additional utility when synchronized with real-time squad updates released by governing bodies such as the English Football Association and UEFA. Integration platforms pull historical head-to-head records alongside current form streaks to generate adjusted odds that reflect both statistical likelihood and market movement.
Studies conducted by university sports science departments demonstrate that incorporating player workload data from domestic cup fixtures improves forecast accuracy for midweek league matches. Those models then transfer directly into accumulator chains where a football banker anchors subsequent racing legs. The process relies on standardized data schemas that convert possession percentages and shot locations into comparable numerical scores suitable for joint probability calculations.
Track Statistics and Their Role in Multi-Sport Chains
Horse racing records supply time-based measurements recorded at consistent intervals along each course. Official handicappers publish speed figures adjusted for weight carried, distance traveled, and prevailing ground conditions. Trainers release declarations that include recent workout times and veterinary notes, while stewards publish going reports that influence pace projections. Data fusion systems ingest these elements alongside form ratings to produce normalized performance scores that align with football-derived probabilities.
June 2026 saw several major racing festivals publish expanded sectional timing datasets through industry partnerships, enabling finer calibration of pace predictions. Modelers combine these fresh inputs with historical trainer and jockey strike rates to refine selections that follow football legs in accumulator structures. The resulting outputs account for variables such as stall position and pace maps that rarely appear in standard form guides yet materially affect finishing positions.
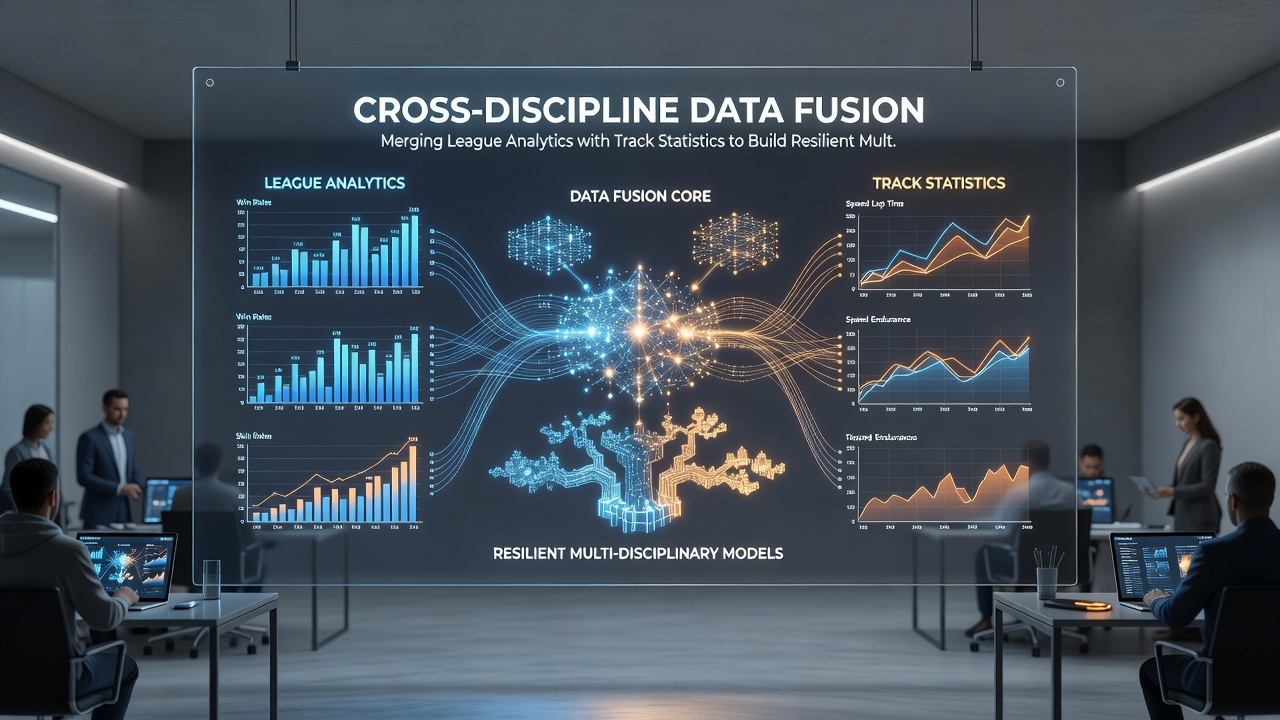
Practical Implementation of Fusion Techniques
Operators construct joint probability tables that map football match likelihoods against racing outcomes using shared variance parameters. Machine learning pipelines trained on multi-year archives identify non-linear relationships between league fixture congestion and subsequent trainer performance at specific tracks. These pipelines output adjusted confidence bands rather than single-point estimates, allowing bettors to size stakes according to the width of each interval.
One documented approach applies Bayesian updating across sports boundaries. After each football result posts, the system refreshes prior distributions for linked racing selections using conditional probabilities derived from historical cross-sport performance clusters. This method replaces static accumulator pricing with dynamic recalibration that responds to live developments while preserving overall chain integrity.
Geographic and Regulatory Context in Mid-2026
Reports compiled by the Australian Gambling Research Centre indicate rising interest in cross-sport modeling among professional syndicates operating across multiple jurisdictions. Separate analysis from the University of Nevada Center for Gaming Research highlights how operators in regulated markets apply similar fusion layers to manage exposure across football and racing products. These developments occur against a backdrop of evolving tax structures and data-sharing requirements that encourage transparent modeling practices.
Conclusion
Cross-discipline data fusion continues to evolve through incremental refinement of shared statistical frameworks. League analytics and track statistics supply complementary signals that, when combined, produce accumulator structures with measurable resilience to single-leg variance. Continued expansion of standardized datasets across both sports supports further calibration of these models throughout 2026 and beyond.